How to Setup the Dell Pro Max 16 Plus with Qualcomm Inference Card in Linux
Summary: Learn how to setup the Dell Pro Max 16 Plus MB16250 with Qualcomm Inference Card in Linux.
Instructions
Setting up the Dell Pro Max 16 Plus with Qualcomm Inference Card in Linux
Welcome to your Dell Pro Max 16 Plus with Qualcomm AI100 Inference Card!
Follow these one-time setup steps below to get the card ready for AI inferencing workloads using Ubuntu 24.04 on the Dell Pro Max 16 Plus workstation. This ensures that the workstation and card have the right software and configuration baselines setup to jump right into using the card.
-
Verifying the AI100 Card Installation.
Use the followinglspcicommand to verify that the card is installed on the laptop:lspci | grep Qualcomm
This command displays two (2) Qualcomm a100 PCIe device entries for the AI100 card.dell@dell:~$ lspci | grep Qualcomm 04:00.0 Processing accelerators: Qualcomm Technologies, Inc Device a100 05:00.0 Processing accelerators: Qualcomm Technologies, Inc Device a100 dell@dell:~$ -
Updating the BIOS on the Dell Pro Max 16 Plus workstation.
Update the workstation BIOS to ensure that the laptop has the latest support for the AI100 inferencing card. Use the following commands to check for BIOS updates and then upgrade if an update is available:
Commands to check for BIOS updates:sudo fwupdmgr refresh --force sudo fwupdmgr upgrade
Sample output updating to the latest BIOS.dell@dell:~$ sudo fwupdmgr refresh --force Updating lvfs Downloading… [*************************************] Successfully downloaded new metadata: 7 local devices supported dell@dell:~$ sudo fwupdmgr upgrade Devices with no available firmware updates: • Integrated Webcam 8M • PC811 SED SK hynix 2048GB • TPM • UEFI Device Firmware • UEFI dbx • USB4 host controller Perform operation? [Y|n]: Y Waiting… [***************************************] Successfully installed firmware Do not turn off your computer or remove the AC adapter while the update is in progress. An update requires a reboot to complete. Restart now? [y|N]:
Verify BIOS version 2.22 or greater is installed using thedmidecodecommand: Checking existing BIOS firmware version.sudo dmidecode -t 0 -
Updating the Ubuntu Operating System (OS) on your Dell Pro Max 16 Plus workstation
On the next update to the Ubuntu OS on the workstation, support for the AI100 inference card is integrated into Ubuntu 24.04. Updating Ubuntu ensures that the latest kernel modules and AI100 firmware updates are available for your card.
To update Ubuntu - either use the Ubuntu "Software Updater" in the desktop Apps menu, or use the following commands in a Terminal:
Commands to update your Ubuntu software in the Terminal:sudo apt-get update sudo apt-get upgrade sudo rebootOnce the laptop downloads, installs, and updates Ubuntu, reboot the workstation to ensure any boot time changes for the kernel take place.
Verify that your updated Ubuntu kernel is version 6.14.0-1017-oem or newer. This version includes the signed kernel modules that support your AI100 with Secure Boot enabled. Use the following command to check your kernel version.
Verifying that the Linux kernel is version 6.14.0-1017-oem or newer.dell@dell:~$ uname -r 6.14.0-1017-oemdell@dell:~$ uname -r 6.14.0-1017-oem
Next verify the Linux-firmware package that includes the AI100 firmware is version 2.22 or greater using this command-line command:
Verifying the Linux-firmware is version 2.22 or greater.dell@dell:~$ dpkg-query --list linux-firmware Desired=Unknown/Install/Remove/Purge/Hold | Status=Not/Inst/Conf-files/Unpacked/halF-conf/Half-inst/trig-aWait/Trig-pend |/ Err?=(none)/Reinst-required (Status,Err: uppercase=bad) ||/ Name Version Architecture Description +++-==============-================================-============-================================= ii linux-firmware 20240318.git3b128b60-0ubuntu2.22 amd64 Firmware for Linux kernel drivers dell@dell:~$ -
Updating GRUB Kernel Parameters.
To fully use the Qualcomm AI100 inferencing card, disable the feature called PCIe Access Control System (ACS). This is required to support tensor slicing fully using both AI100 devices on the Qualcomm AI100 card. Disable ACS on the PCIe switch on the AI100 card. This allows full data access between the two AI100 devices and all 64 GB of onboard RAM when running inference across both.This is done by passing a Linux kernel parameter that is added to the GRUB configuration to support the Qualcomm AI100 inferencing card. Kernel parameters are configurations passed to the Linux kernel during boot that instructs the kernel how to configure certain features. In this case, ACS is being disabled for the AI100 card. Adding a kernel parameter to the GRUB configuration file does this.
Open the GRUB configuration file with root privileges using a text editor.
Edit the GRUB configuration file/etc/default/grub.sudo nano /etc/default/grubsudo nano /etc/default/grub
Edit theGRUB_CMDLINE_LINUX_DEFAULTline to add thepci=disable_acs_redir(disable ACS on the AI100 card PCIe switch). Be sure to have the exact syntax below. Also ensure that there is only oneGRUB_CMDLINE_LINUX_DEFAULTline in the/etc/default/grubfile (merge kernel options if necessary, onto one line).
ChangeGRUB_CMDLINE_LINUX_DEFAULTline.GRUB_CMDLINE_LINUX_DEFAULT="quiet splash pci=disable_acs_redir=03:00.0\;03:01.0"Press CTRL+X, select Y, and press enter to save the configuration changes. Now run the following and reboot to take effect.
Regenerate the GRUB configuration.sudo update-grub sudo rebootVerify the changes using the following commands after the reboot.
Verify GRUB configuration changes.dell@dell:~$ cat /proc/cmdline BOOT_IMAGE=/boot/vmlinuz-6.14.0-1016-oem root=UUID=cd20aec8-6b44-45f7-bca5-307240cec24b ro quiet splash pci=disable_acs_redir=03:00.0;03:01.0 vt.handoff=7dell@dell:~$ cat /proc/cmdline BOOT_IMAGE=/boot/vmlinuz-6.14.0-1016-oem root=UUID=cd20aec8-6b44-45f7-bca5-307240cec24b ro quiet splash pci=disable_acs_redir=03:00.0;03:01.0 vt.handoff=7
Check that ACS is disabled using dmesg. Messages for "Configured ACS" display as below:dell@dell:~$ sudo dmesg | grep ACS [ 0.000000] Command line: BOOT_IMAGE=/boot/vmlinuz-6.14.0-1016-oem root=UUID=cd20aec8-6b44-45f7-bca5-307240cec24b ro quiet splash pcie_port_m=force pci=disable_acs_redir=03:00.0;03:01.0 vt.handoff=7 [ 0.141658] Kernel command line: BOOT_IMAGE=/boot/vmlinuz-6.14.0-1016-oem root=UUID=cd20aec8-6b44-45f7-bca5-307240cec24b ro quiet splash pcie_port_m=force pci=disable_acs_redir=03:00.0;03:01.0 vt.handoff=7 [ 0.741030] pci 0000:03:00.0: Configured ACS to 0x0000 [ 0.745422] pci 0000:03:01.0: Configured ACS to 0x0000 -
Install Docker
The fastest path to running inference on the AI100 card is to use prebuilt AI100 Docker containers that include support for the Qualcomm AI100 inference card. The prebuilt Docker container provides a ready-to-go environment to run the inference workloads. The container includes the Qualcomm AI100 Platform and Apps SDKs and toolchain, Python environment, Qualcomm Efficient Transformers for compiling AI models and running inferences, as well as including ready to use vLLM and Triton support for the AI100 inferencing card.
To install Docker in Ubuntu, use the following command:
sudo snap install docker
To run docker as a normal user, run the following commands.
Commands to run docker as a normal user.# create and join the docker group sudo addgroup --system docker sudo adduser $USER docker newgrp docker # disable and re-enable the docker snap if you added the group while Docker Engine was running sudo snap disable docker sudo snap enable docker# create and join the docker group sudo addgroup --system docker sudo adduser $USER docker newgrp docker # disable and re-enable the docker snap if you added the group while Docker Engine was running sudo snap disable docker sudo snap enable docker
Prefixing all docker commands with sudo is required if the user is not added to the docker group:sudo docker run ...Reference: Docker Snap
Alternatively, Docker can be installed using apt Debian Docker Docs
Once Docker is installed, test the installation as follows:
Verify the Docker installs with hello-world:dell@dell:~$ docker run hello-world Unable to find image 'hello-world:latest' locally latest: Pulling from library/hello-world 17eec7bbc9d7: Pull complete Digest: sha256:d4aaab6242e0cace87e2ec17a2ed3d779d18fbfd03042ea58f2995626396a274 Status: Downloaded newer image for hello-world:latest Hello from Docker! This message shows that your installation appears to be working correctly. ... -
The Dell Pro Max 16 Plus workstation AI100 inference card is now ready to go!
This completes the one-time setup required to use the AI100 inferencing card. The next sections show how to use AI100 tools to see the status of the card and run initial simple inference to verify that the AI100 card is operational.
-
Checking the AI100 card
Check the AI100 card and run initial inference by using a prebuilt AI100 Docker container containing all the AI100 Platform and Apps SDKs, toolchain, and vLLM and Triton inferencing tools required to use the card.
If this is the first time running the AI100 Docker container, this command also fetches the container. The AI100 Docker container image is ~14 GB download. To start the AI100 Docker container, use the following command:
Start the AI100 Docker container.docker run --rm -it \ --privileged \ --device=/dev/accel/accel1 \ --device=/dev/accel/accel2 \ --network host \ --ulimit nofile=1048576 \ -e OMP_NUM_THREADS=8 \ ghcr.io/quic/cloud_ai_inference_ubuntu24:1.20.6.0 \ /bin/bash
Once the AI100 Docker container has been fetched and run, output like this display on-screen:
Sample output after starting the AI100 Docker container.dell@dell:~$ docker run --rm -it --device=/dev/accel/accel1 --device=/dev/accel/accel2 --network host --ulimit nofile=1048576 -e OMP_NUM_THREADS=8 -v ~/Downloads/qwen3_coder_qpc:/root/qpc/ ghcr.io/quic/cloud_ai_inference_ubuntu24:1.20.6.0 /bin/bash ================================== == Qualcomm Cloud AI Containers == ================================== Platform SDK version: 1.20.6.0 Apps SDK version: 1.20.6.0 This container image and its contents are governed by the terms of the license at /usr/share/doc/CONTAINER_LICENSE.txt. By pulling and using the container, you accept the terms and conditions of this license. root@dell:~#dell@dell:~$ docker run --rm -it --device=/dev/accel/accel1 --device=/dev/accel/accel2 --network host --ulimit nofile=1048576 -e OMP_NUM_THREADS=8 -v ~/Downloads/qwen3_coder_qpc:/root/qpc/ ghcr.io/quic/cloud_ai_inference_ubuntu24:1.20.6.0 /bin/bash ================================== == Qualcomm Cloud AI Containers == ================================== Platform SDK version: 1.20.6.0 Apps SDK version: 1.20.6.0 This container image and its contents are governed by the terms of the license at /usr/share/doc/CONTAINER_LICENSE.txt. By pulling and using the container, you accept the terms and conditions of this license. root@dell:~#
Use the AI100qaic-util -qcommand to provide textual output of the state of the AI100 card, as in the following sample output.
Sample output forqaic-util -qroot@dell:~# qaic-util -q LRT QC_IMAGE_VERSION: LRT.AIC.13.2.1.20.6.0 LRT IMAGE_VARIANT: LRT.AIC.REL Number of devices queried: 2 QID 0 Status:Ready ...A grid status view is possible using the
Sample idle output forqaic-util -t1 command which periodically updates card status. The following sample output shows the AI100 card at idle. The AI100 card includes two AI100 devices, each with 16 Neural Signal Processor (NSP) compute cores. Each device shows 32 GB of memory, totaling 64 GB on the card:qaic-util -t 1.root@dell:~# qaic-util -t 1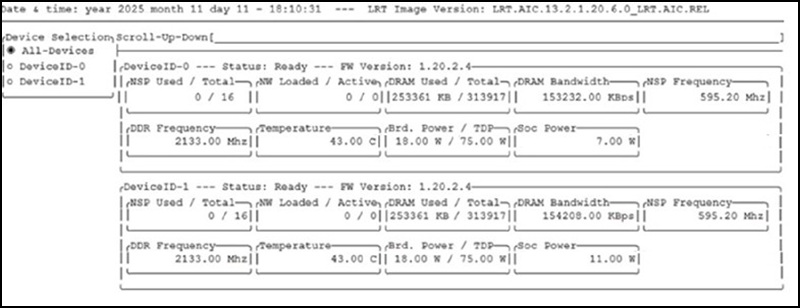
Here is another sampleqaic-utiloutput while the AI100 card is running an AI inferencing workload. In this case, it shows a larger model - qwen3-coder:30b. The output shows that all 16 NSPs are being used on each AI100 device, the card temperature has increased to 47C from lower idle temperatures, that each AI100 part is using ~13 GB each, totaling 26 GB for the model, the overall power used for the board is 51 out of a max of 75 W, and that the NSP frequency has increased for the workload to 1100 Mhz.
Sample output for AI100 running inference usingqaic-util -t 1.root@dell:~# qaic-util -t 1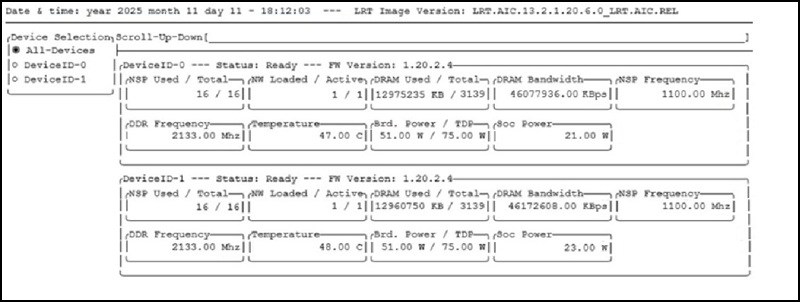
To reset the AI100 card, use theqaic-util -scommand. This command requires hardware permission inside the container requiring the "-privileged" command-line parameter when running the container. The following sample output shows usingqaic util -sfollowed byqaic-util -t1 to monitor the card status. Invalid field values as in the sample output below display until the card completes the reset:
Sample output of AI100 card reset usingqaic-util -sandqaic-util -t 1.root@dell:~# qaic-util -s Resetting all devices… 0000:04:00.0: 0000:04:00.0 success 0000:05:00.0: 0000:05:00.0 success root@dell:~# qaic-util -t 1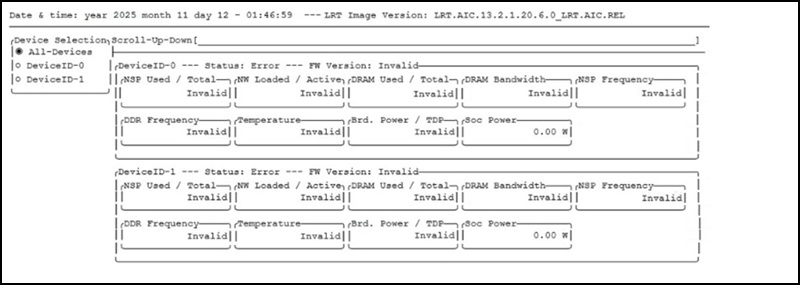
Use a single system prompt to bring up the AI100 card status using the AI100 Docker container as follows.
Start the AI100 Docker container.docker run --rm -it \ --privileged \ --device=/dev/accel/accel1 \ --device=/dev/accel/accel2 \ --network host \ --ulimit nofile=1048576 \ -e OMP_NUM_THREADS=8 \ ghcr.io/quic/cloud_ai_inference_ubuntu24:1.20.6.0 \ qaic-util -t 1docker run --rm -it \ --privileged \ --device=/dev/accel/accel1 \ --device=/dev/accel/accel2 \ --network host \ --ulimit nofile=1048576 \ -e OMP_NUM_THREADS=8 \ ghcr.io/quic/cloud_ai_inference_ubuntu24:1.20.6.0 \ qaic-util -t 1Note: Error output lines are seen when running theqaic-util -sandqaic-util -t 1commands and in its grid output showing "Invalid" for Temperature and Board Power/TDP and "0.00 W" shown for SoC Power. There are changes in flight upstream to address this in upcoming Ubuntu OS and AI100 Docker container updates. -
Running Test Inference
This section shows how to run a quick inference test on the AI100 card. Use this inference test to verify the functionality of the AI100 card.
Use the command-line command
qaic-runnerto run the first test inference workload. Use-dto specify the target AI100 device,-ato specify the number of NSPs to use, and-nfor the number of iterations:
Sample test inference usingqaic-runner.docker run --rm -it \ --device=/dev/accel/accel1 \ --device=/dev/accel/accel2 \ --network host \ --ulimit nofile=1048576 \ -e OMP_NUM_THREADS=8 \ ghcr.io/quic/cloud_ai_inference_ubuntu24:1.20.6.0 \ qaic-runner -t /opt/qti-aic/test-data/aic100/v2/1nsp/1nsp-conv-hmx/ -a 16 -n 5000 -d 0docker run --rm -it \ --device=/dev/accel/accel1 \ --device=/dev/accel/accel2 \ --network host \ --ulimit nofile=1048576 \ -e OMP_NUM_THREADS=8 \ ghcr.io/quic/cloud_ai_inference_ubuntu24:1.20.6.0 \ qaic-runner -t /opt/qti-aic/test-data/aic100/v2/1nsp/1nsp-conv-hmx/ -a 16 -n 5000 -d 0
Sample output like the following displays on-screen:
Sample output for running test inference.dell@dell:~$ docker run --rm -it \ --device=/dev/accel/accel1 \ --device=/dev/accel/accel2 \ --network host \ --ulimit nofile=1048576 \ -e OMP_NUM_THREADS=8 \ ghcr.io/quic/cloud_ai_inference_ubuntu24:1.20.6.0 \ qaic-runner -t /opt/qti-aic/test-data/aic100/v2/1nsp/1nsp-conv-hmx/ -a 16 -n 5000 -d 0 loading /opt/qti-aic/dev/lib/x86_64/libQAic.so ---- Stats ---- InferenceCnt 5000 TotalDuration 22544us BatchSize 1 Inf/Sec 221788.502 -
Useful Links
The table below includes a list of key and useful AI100 resources and links to start getting the most out of the AI100 inference card.
- Qualcomm AI100 User Guide
: Starting point for all topics AI100 - comprehensive AI100 user guide
- Qualcomm Efficient Transformers Library
- QAIC Containers
- QAIC Containers - 24.04 latest
- Qualcomm Efficient Transformers Developer Blog
- http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/ Note: This URL is not an HTTPS link. Use at your own risk.
Note: Go to the support site and use the filter keyword Linux to see other Dell articles associated with the Dell Pro Max 16 Plus MB16250 with Al100 laptop: - Qualcomm AI100 User Guide
-
AI100 Prebuilt Models
The table below includes a snapshot of AI models that are prebuilt to run inside the AI100 Docker container (using vLLM for example).
The AI100 inference card runs models using a Qualcomm Program Container (QPC) format. QPCs can be built from Huggingface models using the AI100 Platform and Apps SDKs, or use prebuilt AI model QPCs from the online Zentree catalog at the following link. QPCs are built targeting the number of AI100 devices on the card - the Dell Pro Max 16 Plus with Qualcomm Inference Card supports QPCs built to run on one or two SoCs (AI100 System on a Chip). A QPC built for two AI100 devices uses tensor slicing to be able to run large models using the compute of two AI100 devices across the full 64 GB of memory on the card.
See the catalog tab at the following link for the http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/
Note: These URLs are not HTTPS links. Use at your own risk.Model Family Model Architecture Representative Model Model Type QAIC SDK Version QEff Auto Class Task QPC Link BERT BERTModel BAAI/bge-large-en-v1.5 Embedding model 1.19.6 QEFFAutoModel Text embedding http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.19.6/bge-large-en-v1.5/ BERT BERTModel BAAI/bge-m3 Embedding model 1.19.6 QEFFAutoModel Text embedding http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.19.6/bge-m3/ BERT BERTModel BAAI/bge-base-en-v1.5 Embedding model 1.19.6 QEFFAutoModel Text embedding http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.19.6/bge-base-en-v1.5/ DeepSeek-R1-Distill-Llama LlamaForCausalLM Valdemardi/DeepSeek-R1-Distill-Llama-70B-AWQ Text-only language model 1.20.4 QEFFAutoModelForCausalLM Text-generation http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/DeepSeek-R1-Distill-Llama-70B-AWQ/ DeepSeek-R1-Distill-Llama LlamaForCausalLM casperhansen/deepseek-r1-distill-llama-8b-awq Text-only language model 1.20.4 QEFFAutoModelForCausalLM Text-generation http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/deepseek-r1-distill-llama-8b-awq/ DeepSeek-R1-Distill-Qwen Qwen2ForCausalLM Valdemardi/DeepSeek-R1-Distill-Llama-32B-AWQ Text-only language model 1.20.4 QEFFAutoModelForCausalLM Text-generation http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/DeepSeek-R1-Distill-Qwen-32B-AWQ/ DeepSeek-R1-Distill-Qwen Qwen2ForCausalLM casperhansen/deepseek-r1-distill-qwen-7b-awq Text-only language model 1.20.4 QEFFAutoModelForCausalLM Text-generation http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/deepseek-r1-distill-qwen-7b-awq/ Gemma3 Gemma3ForConditionalGeneration google/gemma-3-4b-it Multimodal language model 1.20.4 QEFFAutoModelForImageTextToText Vision-language models (text + image gen) http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/gemma-3-4b-it/ GPT-OSS GptOssForCausalLM openai/gpt-oss-20b Text-only language model 1.20.4 QEFFAutoModeForCausalLM Text generation http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/gpt-oss-20b/ Granite-3.2 GraniteForCausalLM ibm-granite/granite-3.2-8b-instruct Text-only language model 1.20.4 QEFFAutoModelForCausalLM Text generation http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/granite-3.2-8b-instruct/ Granite-3.3 GraniteForCausalLM ibm-granite/granite-3.3-8b-instruct Text-only language model 1.20.4 QEFFAutoModelForCausalLM Text generation http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/granite-3.3-8b-instruct/ Llama 3.1 LlamaForCausalLM meta-llama/Llama-3.1-8B-Instruct Text-only language model 1.20.4 QEFFAutoModelForCausalLM Text generation http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/Llama-3.1-8B/ Llama 3.1 Nemotron LlamaForCausalLM ibnzterrell/Nvidia-Llama-3.1-Nemotron-70B-Instruct-HF-AWQ-INT4 Text-only language model 1.20.4 QEFFAutoModelForCausalLM Text generation http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/Nvidia-Llama-3.1-Nemotron-70B-Instruct-HF-AWQ-INT4/ Llama 3.1 Nemotron LlamaForCausalLM nvidia/Llama-3.1-Nemotron-Nano-8B-v1 Text-only language model 1.20.4 QEFFAutoModelForCausalLM Text generation http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/Llama-3.1-Nemotron-Nano-8B-v1/ Llama 3.2 LlamaForCausalLM meta-llama/Llama-3.2-1B Text-only language model 1.20.4 QEFFAutoModelForCausalLM Text generation http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/Llama-3.2-1B/ Llama 3.2 LlamaForCausalLM meta-llama/Llama-3.2-3B Text-only language model 1.20.4 QEFFAutoModelForCausalLM Text generation http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/Llama-3.2-3B/ Llama 3.2 LlamaForCausalLM meta-llama/Llama-3.2-3B-Instruct Text-only language model 1.20.4 QEFFAutoModelForCausalLM Text generation http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/Llama-3.2-3B-Instruct/ Llama 3.2 MllamaForConditionalGeneration meta-llama/Llama-3.2-11B-Vision-Instruct Multimodal language model 1.20.4 QEFFAutoModelForImageTextToText Vision-language models (text + image gen) http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/Llama-3.2-11B-Vision-Instruct/ Llama 3.2 Instruct LlamaForCausalLM meta-llama/Llama-3.2-1B-Instruct Text-only language model 1.20.4 QEFFAutoModelForCausalLM Text generation http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/Llama-3.2-1B-Instruct/ Llama 3.x LlamaForCausalLM Target: Meta-Llama-3.1-70B-Instruct-AWQ-INT4
Draft: Llama-3.2-1B-InstructSpeculative Decode (SpD) 1.20.4 QEFFAutoModelForCausalLM Text generation http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/spd/meta-llama/ Llama 3.x LlamaForCausalLM Target: casperhansen/llama-3.3-70b-instruct-awq
Draft: meta-llama/Llama-3.2-1B-InstructSpeculative Decode (SpD) 1.20.4 QEFFAutoModelForCausalLM Text generation http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/spd/llama33-70b-awq__draft-llama32-1b/ Mistral MistralForCausalLM mistralai/Mistral-7B-Instruct-v0.1 Text-only language model 1.20.4 QEFFAutoModelForCausalLM Text-generation http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/Mistral-7B-Instruct-v0.1/ Phi-4 Phi3ForCausalLM microsoft/phi-4 Text-only language model 1.20.4 QEFFAutoModelForCausalLM Text generation http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/phi-4/ Qwen3 Qwen3Moe Qwen/Qwen3-30B-A3B-Instruct-2507 Text-only language model 1.20.4 QEFFAutoModelForCausalLM Text generation http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/Qwen3-30B-A3B-Instruct-2507/ Qwen3-Coder Qwen3Moe Qwen/Qwen3-Coder-30B-A3B-Instruct Text-only language model 1.20.4 QEFFAutoModelForCausalLM Code generation http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/Qwen3-Coder-30B-A3B-Instruct/ Sarvamai Sarvamai sarvamai/sarvam-1 Text-only language model 1.20.4 QEFFAutoModelForCausalLM Text generation Indian language focus http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/sarvam-1/ SDXL StableDiffusionForTextToImage stabilityai/stable-diffusion-xl-base-1.0 Multimodal language model 1.20.4 AutoPipelineForText2Image Vision-language models (text + image gen) http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/stable-diffusion-xl-base-1.0/ SDXL Turbo StableDiffusionForTextToImage stabilityai/sdxl-turbo Multimodal language model 1.20.4 AutoPipelineForText2Image Vision-language models (text + image gen) http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/sdxl_turbo/ Whisper Whisper openai/whisper-base Audio model 1.20.4 QEFFAutoModelForSpeechSeq2Seq Automatic speech recognition (transcription) http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/whisper-base/ Whisper Whisper openai/whisper-large-v3-turbo Audio model 1.20.4 QEFFAutoModelForSpeechSeq2Seq Automatic speech recognition (transcription) http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/whisper-large-v3-turbo/ Whisper Whisper openai/whisper-large Audio model 1.20.4 QEFFAutoModelForSpeechSeq2Seq Automatic speech recognition (transcription) http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/whisper-large/ Whisper Whisper openai/whisper-medium Audio model 1.20.4 QEFFAutoModelForSpeechSeq2Seq Automatic speech recognition (transcription) http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/whisper-medium/ Whisper Whisper openai/whisper-small Audio model 1.20.4 QEFFAutoModelForSpeechSeq2Seq Automatic speech recognition (transcription) http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/whisper-small/ Whisper Whisper openai-whisper-tiny Audio model 1.20.4 QEFFAutoModelForSpeechSeq2Seq Automatic speech recognition (transcription) http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/whisper-tiny/ XLM-RoBERTa XLMRobertaModel intfloat/multilingual-e5-large Embedding model 1.20.4 QEFFAutoModel Text embedding http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.20.4/multilingual-e5-large/ XLM-RoBERTa XLMRobertaModel intfloat/multilingual-e5-small Embedding model 1.19.6 QEFFAutoModel Text embedding http://qualcom-qpc-models.s3-website-us-east-1.amazonaws.com/QPC/1.19.6/multilingual-e5-small/