Measuring concurrent coding agent capacity across nine agentic tasks on the Dell PowerEdge™ R770 rack server with Intel® Xeon® 6 6760P processors and NVIDIA RTX™ PRO 6000 Blackwell Server Edition GPUs
Agent Density at Enterprise Scale
DISCLAIMER: Performance varies by hardware and software configurations, including testing conditions, system settings, application complexity, the quantity of data, batch sizes, software versions, libraries used, and other factors. The results of performance testing provided are intended for informational purposes only and should not be considered as a guarantee of actual performance.
Measuring concurrent coding agent capacity across nine agentic tasks on the Dell PowerEdge™ R770 rack server with Intel® Xeon® 6 6760P processors and NVIDIA RTX™ PRO 6000 Blackwell Server Edition GPUs
Dell PowerEdge R770 server platform powered by Intel Xeon 6 processors
Executive summary
Enterprise AI is moving from single-turn assistants to fleets of autonomous coding agents. Each agent runs inside its own isolated sandbox and repeats a two-part loop: it asks a model what to do next, then executes that step by editing files, running builds, executing tests, and calling shell tools. The tool-execution half of that loop lands on the host rather than on the accelerator, so capacity is set by the whole platform and by the task, not by an agents-per-GPU rule of thumb. Sizing an agent service therefore requires three measured answers: how many concurrent agents a server sustains within an agreed service level, which tier sets that ceiling, and the density below which the platform stops being economic to run.
This paper reports that measurement. On a single Dell PowerEdge R770 with two Intel Xeon 6 6760P processors and two NVIDIA RTX PRO 6000 Blackwell GPUs, the Agent Density benchmark grew fleets of identical coding agents one rung at a time, from 1 agent to 1,024, serving Ornith-1.5-35B-A3B-FP8 through vLLM and grading every attempt with the task's own verifier. All nine tasks qualified. The largest fleet each task held within its service level ranged from 120 concurrent agents on the compile-heavy kernel build to more than 1,024 on three tasks that never reached a limit. That more than eightfold spread on one chassis is the result that matters for planning: a single agents-per-server figure will overprovision an inference-dominated fleet by close to an order of magnitude, or underprovision a compile-heavy fleet badly enough to miss the service level in the first week of production. The figures in this paper let a platform team drive chassis count, rack power and the next infrastructure investment from measured evidence rather than estimates.
Key results at a glance
902 concurrent fix-git agents, verified. One Dell PowerEdge R770 held 902 agents inside the task's 900-second latency target and failed at 943. 87% of attempts passed the verifier, and 51.6 verified tasks per minute left the server.
120 to more than 1,024 agents, depending on the task. Nine tasks qualified on the same chassis. The compile-heavy kernel build sized at 120 agents; three tasks held every rung to 1,024 with no limit found.
Task quality held under load: 85% to 99% pass rates. Oversubscription showed up as longer waits for the model, not as wrong answers.
The serving tier sets the ceiling, not the host. At six of seven inference-dominated and mixed densities both GPUs ran 95% to 99% busy, and KV cache peaked at 97% on the reference task, while host CPU averaged 2% to 15% across two Intel Xeon 6 6760P processors.
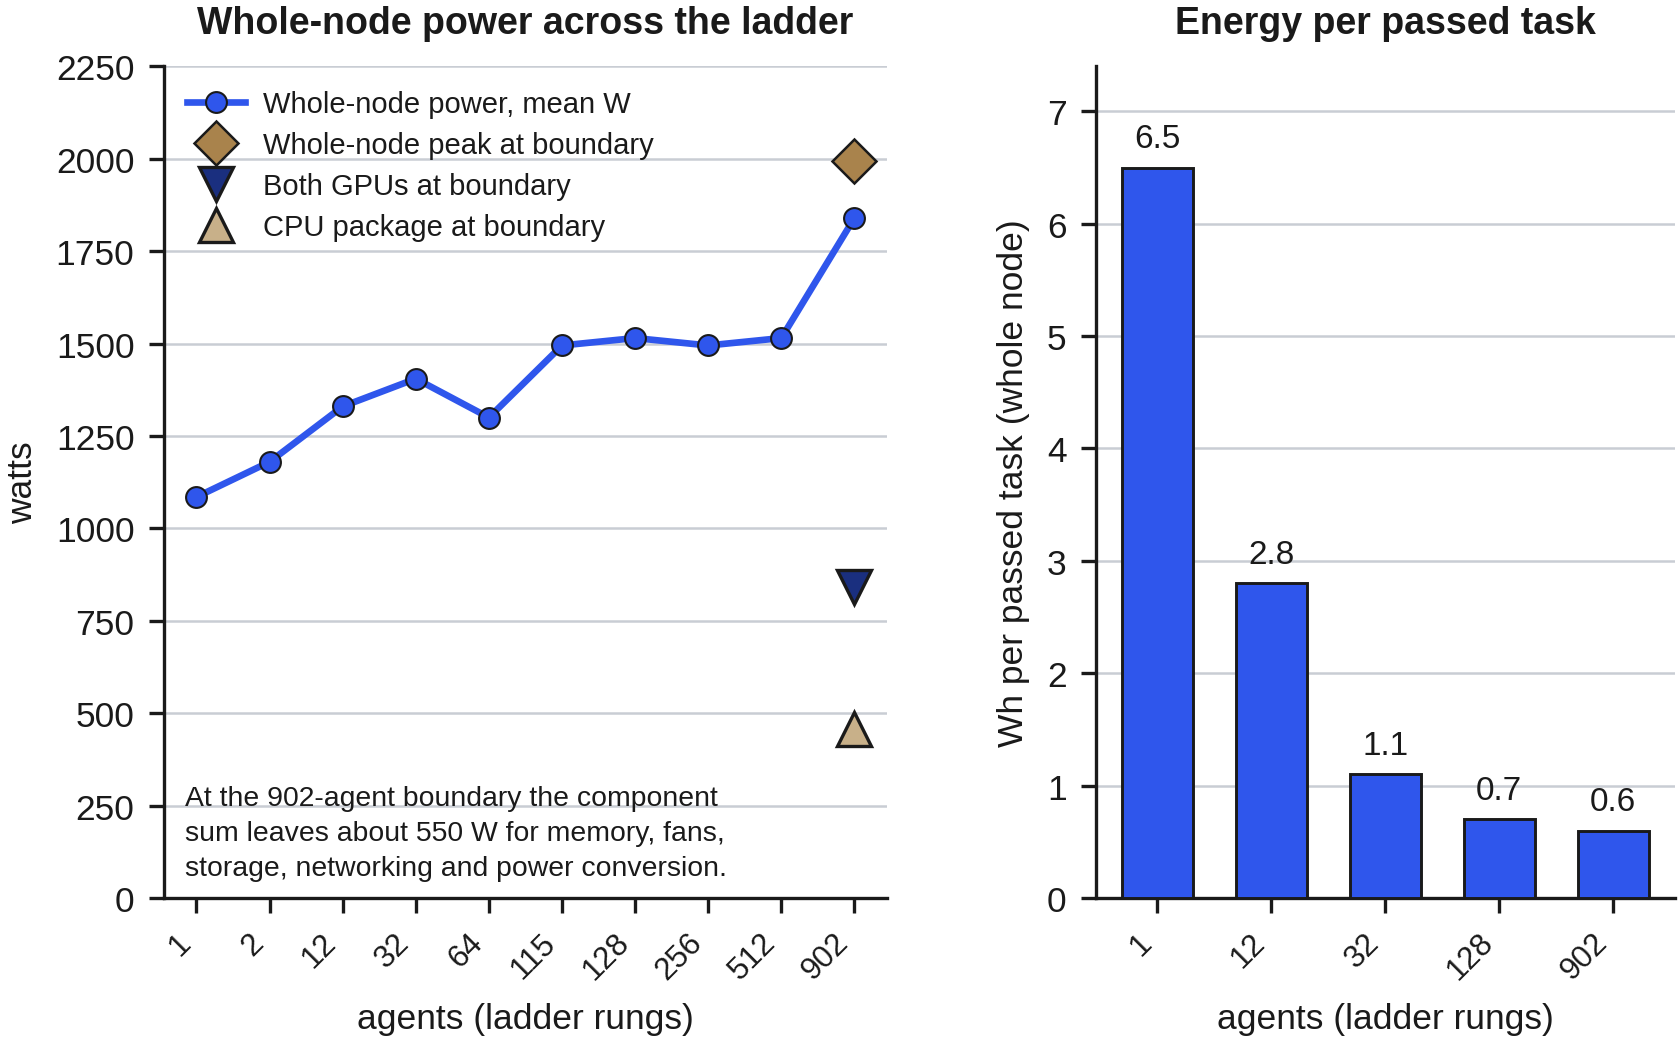
Energy per verified task fell roughly tenfold. Node power rose from about 1.0 kW at one agent to within 1.5 kW and 1.9 kW at the boundary, while verified output rose far faster. On fix-git, energy fell from 6.5 Wh to 0.60 Wh per passed task.
Why agent density needs a service level
Organizations deploying coding agents need one number to plan with: how many concurrent agents a server supports while the work still gets done on time. Existing guidance usually answers a nearby question instead, because the two most common approaches measure characteristics associated with capacity rather than capacity itself.
A universal agents-per-GPU figure. Any figure quoted independently of the task and the service level overlooks the work an agent performs between inference calls. Sandbox startup, compilation, test execution and file operations all consume host resources. In this campaign the same two GPUs supported 120 agents on one task and more than 1,024 on another. A single agents-per-GPU figure cannot represent a spread of more than eight times on the same two GPUs.
A CPU-to-GPU time ratio. The ratio of sandbox core-seconds to GPU-busy seconds is a useful work profile, and this paper publishes it for all nine tasks. It predicts which tier will bind before a ladder is run. On its own it does not establish capacity, because it describes the shape of the work rather than a scaling limit.
Nothing breaks, so the promise decides where to stop
On the reference task, fix-git, no gate threshold was crossed by a hardware or platform fault as agents were added. Verified output kept rising through every rung to 1,024 agents, while attempt latency climbed smoothly alongside it, and no subsystem failed at any level. Elsewhere, three published figures were set by a condition other than the service level: for openssl-selfsigned-cert and kv-store-grpc the next rung breached a measurement-integrity gate, and portfolio-optimization ended on a vLLM preemption, a sign of KV-cache pressure in the serving tier. In each case the published figure is the highest level at which all seven gates held. A curve with no knee has no natural stopping point, so any single number read off it is arbitrary. The machine does not decide when to stop. Only a service-level target does.
This campaign therefore sets one explicit target per task and holds it constant across every rung of the ladder. The 95th-percentile agent attempt time must stay within the task's own deadline: 900 seconds for most tasks, 600 seconds for modernize-scientific-stack, 1,800 seconds for the kernel build and 3,600 seconds for portfolio-optimization. A second gate requires at least 75% of graded attempts to pass the task's verifier. A density that keeps both promises is a density a team can confidently deploy. A density that breaks either one is not, however many agents were technically alive.
Solution architecture
The benchmark runs a single coding task across a fleet of agents, each in an isolated sandbox, and grades every attempt with the task's own verifier. Agent density is the only experimental variable within a run, and all components, including agents, sandboxes, model replicas, the router and telemetry, run on one chassis.
Pipeline stages
Provisioning. The harness creates one Docker sandbox per agent, so a level of N agents starts N sandboxes at once, and releases the whole fleet as one wave.
Quotas are caps, not reservations. The fleet shares all 256 logical CPUs, so the 8-CPU kernel build oversubscribes them above 32 agents.
Execution. Each agent runs an independent loop: assemble context, call the model, run a command inside its sandbox, observe the result, repeat, until it submits a result or reaches its step cap or task deadline.
One attempt per slot. This is a closed single-pass fleet, so a level of N agents produces N graded attempts.
Grading. The task's verifier grades each result inside the same container, with held-out tests copied in only at grading time.
Judgment. Per-agent spans, cgroup counters, host and GPU telemetry, vLLM state and chassis power align on one clock at a two-second cadence, and the harness judges each level against all seven gates before the ladder advances. When a rung fails, a binary search runs between the last rung that held and the first that failed.
This campaign disabled confirmation re-runs, so each published boundary is a single-observation claim, and confidence comes from comparing independent runs of the same task on the same host.
Configuration under test
The operator selects the task and the ladder. Every other parameter stays fixed for the duration of a run, so each level is evaluated under identical conditions.
Configuration under test for the agent density ladder. The table summarizes the fixed and derived benchmark configuration parameters, including density ladder settings, observation windows, tasks, model serving configuration, resource quotas, sandbox policy, service-level policy, and qualification gates used throughout the agent-density evaluation.
Dimension
Setting
Notes
Density ladder
Fixed per run
Core rungs of 1, 2, 12, 32, 64, 115, 128, 256, 512 and 1,024 agents. The 8-CPU kernel build walks 1, 2, 4, 8, 14, 16, 32, 64 and 128. When a core rung fails, a binary search is automatically executed between the last passing rung and the failing rung to find the exact boundary.
Observation window
Derived
Single-pass fleet. Level window to the last verdict of any attempt; goodput window to the last passing verdict (see Terms). Not an operator setting.
Task
Fixed per run
Nine qualified Terminal-Bench tasks spanning inference-dominated, mixed and compute-heavy work profiles. One task per run, fixed across all levels.
Model and serving
Fixed
Ornith-1.5-35B-A3B-FP8 on two single-GPU vLLM replicas, tensor-parallel 1, behind one shared router. 256 concurrent sequences per replica, 512 in flight across both GPUs.
Per-agent quota
Fixed per task
1 CPU and 2,048 MB for seven tasks, 1 CPU and 4,096 MB for portfolio-optimization, 8 CPUs and 8,192 MB for build-linux-kernel-qemu. Caps, not reservations.
Sandbox policy
Fixed
One Docker sandbox per agent. Task content baked into the image. Direct external egress blocked and routed through a proxy.
Service-level policy
Fixed per run
Agent attempt p95 within the task’s own deadline, plus a verifier pass floor of 75%. Goodput and energy ceilings were not configured.
Gate set
Fixed
Version 10. Seven gates covering the service level and the integrity of the measurement itself. See Table 2.
Qualification gates
A level qualifies only when all seven gates hold. The first two are the service level. The remaining five confirm that the measurement itself was sound, which matters because a container failure or a telemetry gap can otherwise be mistaken for capacity.
Qualification gates, gate set version 10. The table shows agent capacity, pass rates, and latency results for nine coding tasks.
Gate
Threshold
Latency ceiling
Agent attempt p95 within the task deadline. Guards against publishing a density at which agents no longer finish on time.
Task pass floor
At least 75% of graded attempts pass, significance-tested. Guards against buying latency with wrong answers.
Agent deadline rate
No more than 10% of attempts stopped by the deadline
Infrastructure success
At least 95% of sandboxes start and are accounted for
Resource faults
No OOM kills above 5%, no GPU XID or ECC errors
Memory pressure
Host memory-stall time is no more than 10%, attributed to the fleet
Measurement integrity
Telemetry coverage of at least 95%, stable GPU identity, no counter resets
Serving queue depth, goodput regression and scaling efficiency are recorded as observations and never end a sweep. One further stop condition sits outside the gate set: a vLLM preemption count above zero marks a level unstable and ends a sweep. Portfolio-optimization is the one published task where this trigger, rather than the service level, set the figure.
Reference architecture
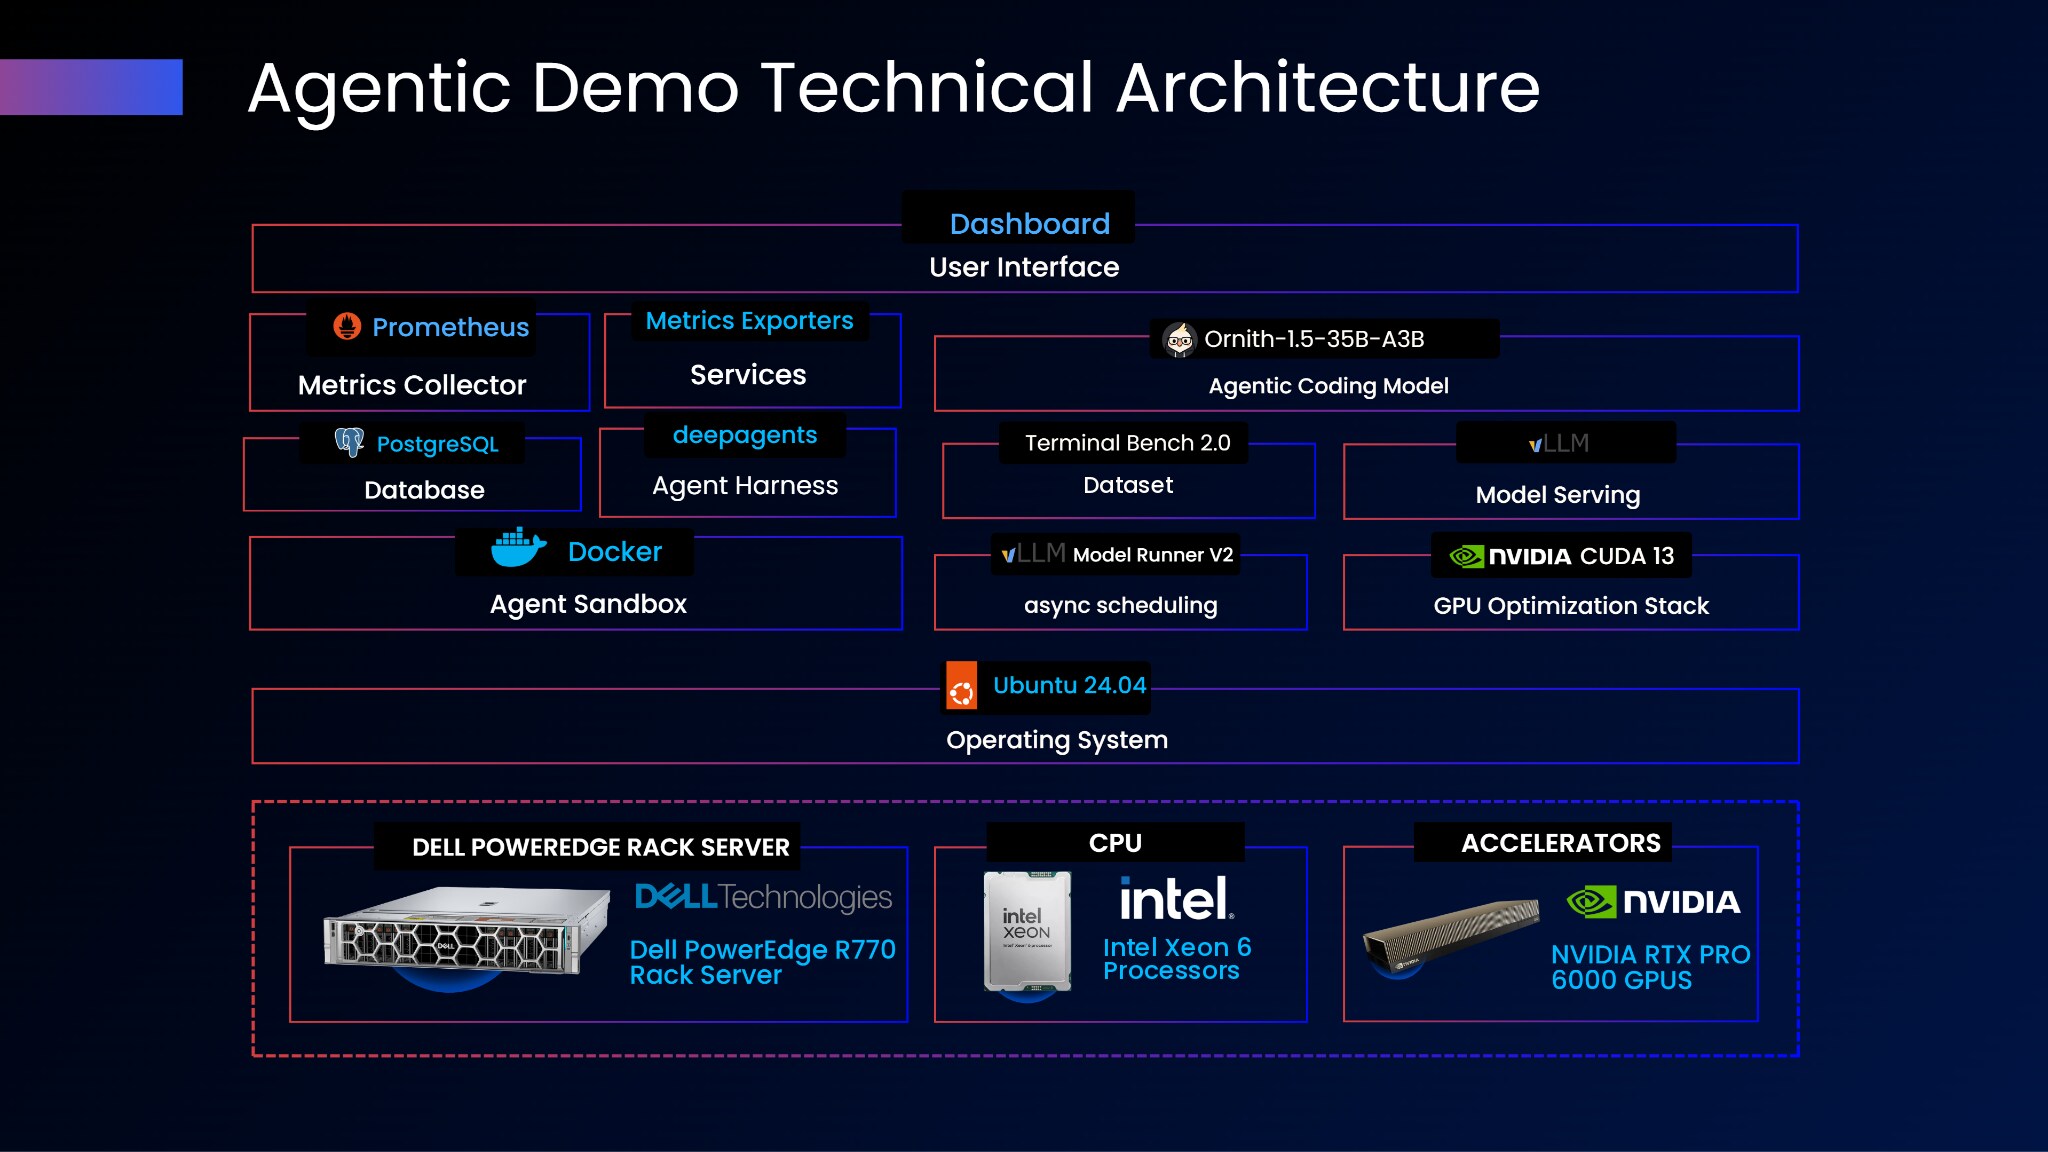
All components run on a single Dell PowerEdge R770 chassis.
Technical architecture of the agent density workload
Performance benchmark
The nine runs behind this paper each walked the density ladder from a single agent to the top rung, grading every attempt with the task's own verifier. The nine tasks are drawn from Terminal-Bench, a public benchmark of hand-written, human-verified terminal tasks that each ship with an objective verifier: eight are unmodified Terminal-Bench 2.0 tasks, and the kernel build, build-linux-kernel-qemu, is taken from the Terminal-Bench 1.0 core registry with its CPU declaration set to 8.
Capacity across nine tasks
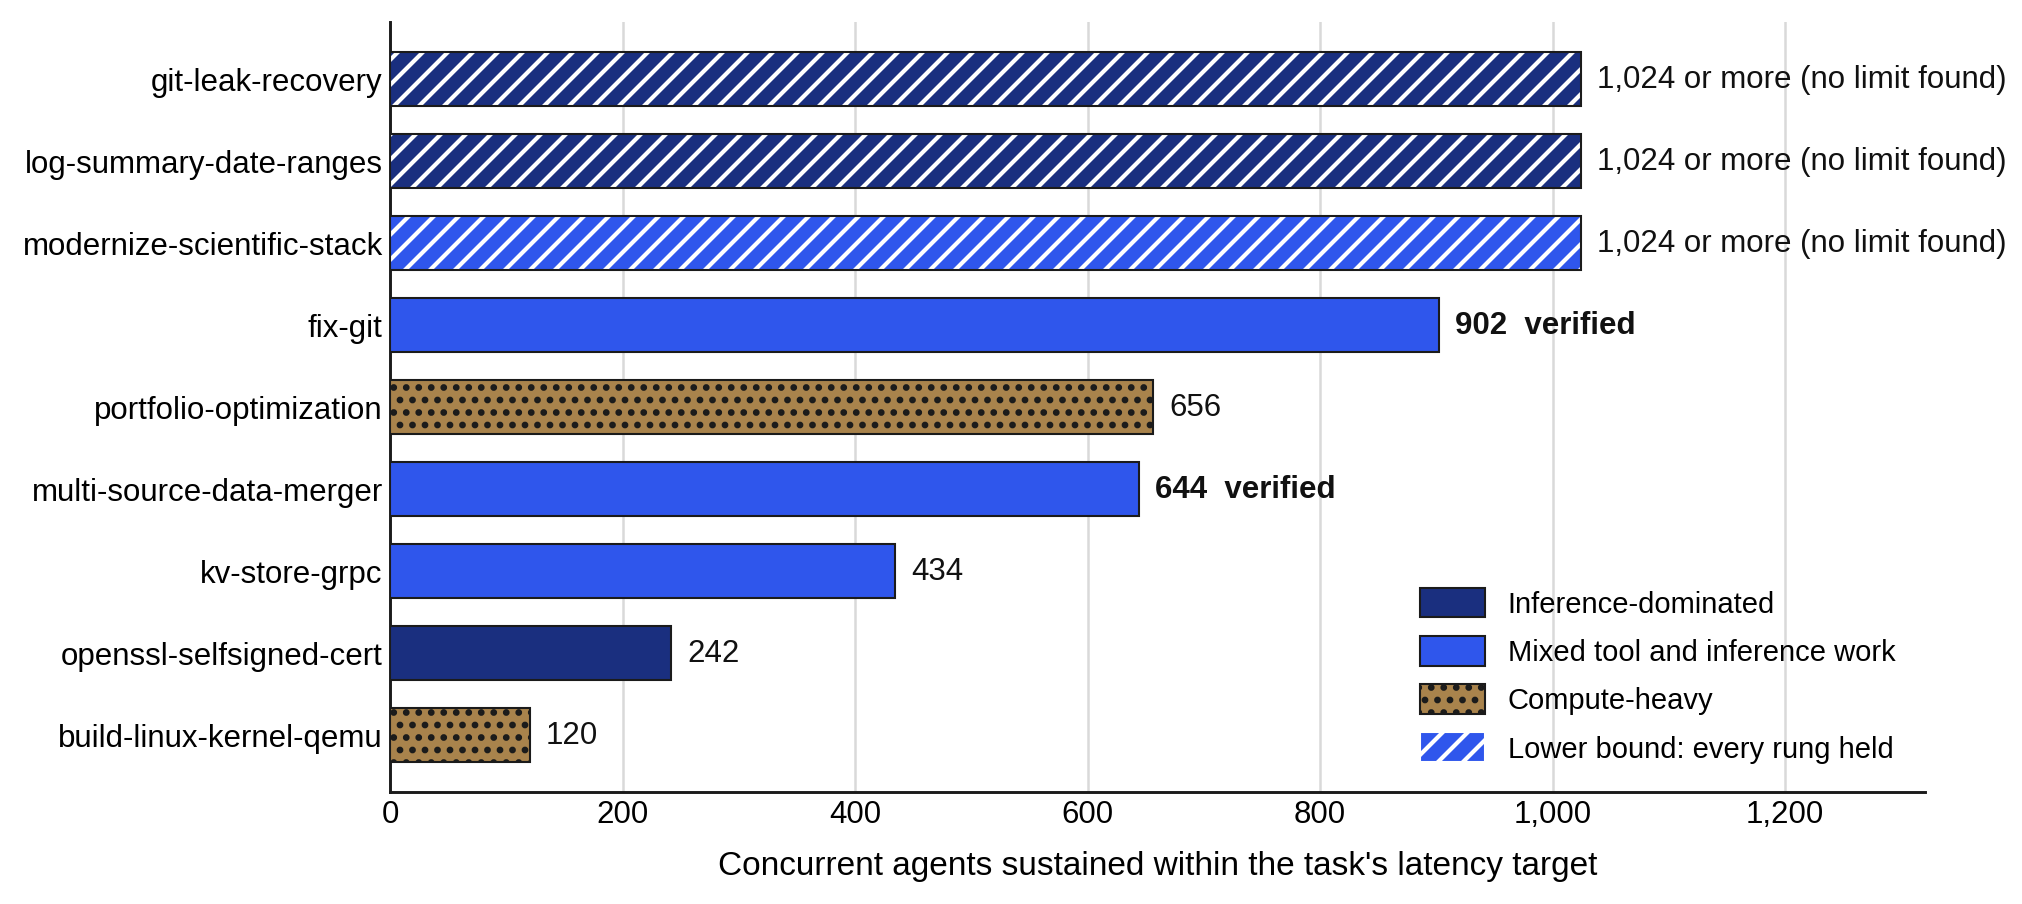
Nine tasks qualified on the same chassis under each task's own latency target. Three held every rung to the top of the ladder and are published as lower bounds, because the machine was never pushed to a limit on them. Two were bracketed by a failing level directly above and are published as verified. The other four are each the highest level at which all seven gates held; for openssl-selfsigned-cert and kv-store-grpc the next rung breached a measurement-integrity gate rather than the service level.
Published agent density per task, where 1,024 or more means every rung of the ladder held and no limit was found. Comparison of agent capacity, task quality, and latency performance across nine benchmark tasks.
Task
Work profile
Fleet size within service level
Confidence
Pass rate
Agent p95 against deadline
git-leak-recovery
Inference-dominated
1,024 or more
High
99%
602 s of 900 s
log-summary-date-ranges
Inference-dominated
1,024 or more
High
98%
380 s of 900 s
modernize-scientific-stack
Mixed
1,024 or more
High
98%
507 s of 600 s
fix-git
Mixed
902, verified
High
87%
891 s of 900 s
portfolio-optimization
Compute-heavy
656
Medium
99%
2,696 s of 3,600 s
multi-source-data-merger
Mixed
644, verified
High
93%
861 s of 900 s
kv-store-grpc
Mixed
434
Medium
85%
437 s of 900 s
openssl-selfsigned-cert
Inference-dominated
242
Medium
98%
276 s of 900 s
build-linux-kernel-qemu
Compute-heavy
120
High
86%
1,639 s of 1,800 s
Fleet size within service level for each task on one Dell PowerEdge R770. Hatched bars are lower bounds: the ladder ended at 1,024 agents with no limit found, so their true capacity is higher than shown
Key takeaway: A single Dell PowerEdge R770 admits fleets of between 120 and more than 1,024 concurrent coding agents depending on the task, at full task quality, under each task's own latency target. The spread is the point. An agents-per-server figure means something only with the task and the service level attached.
Where the ceiling sits
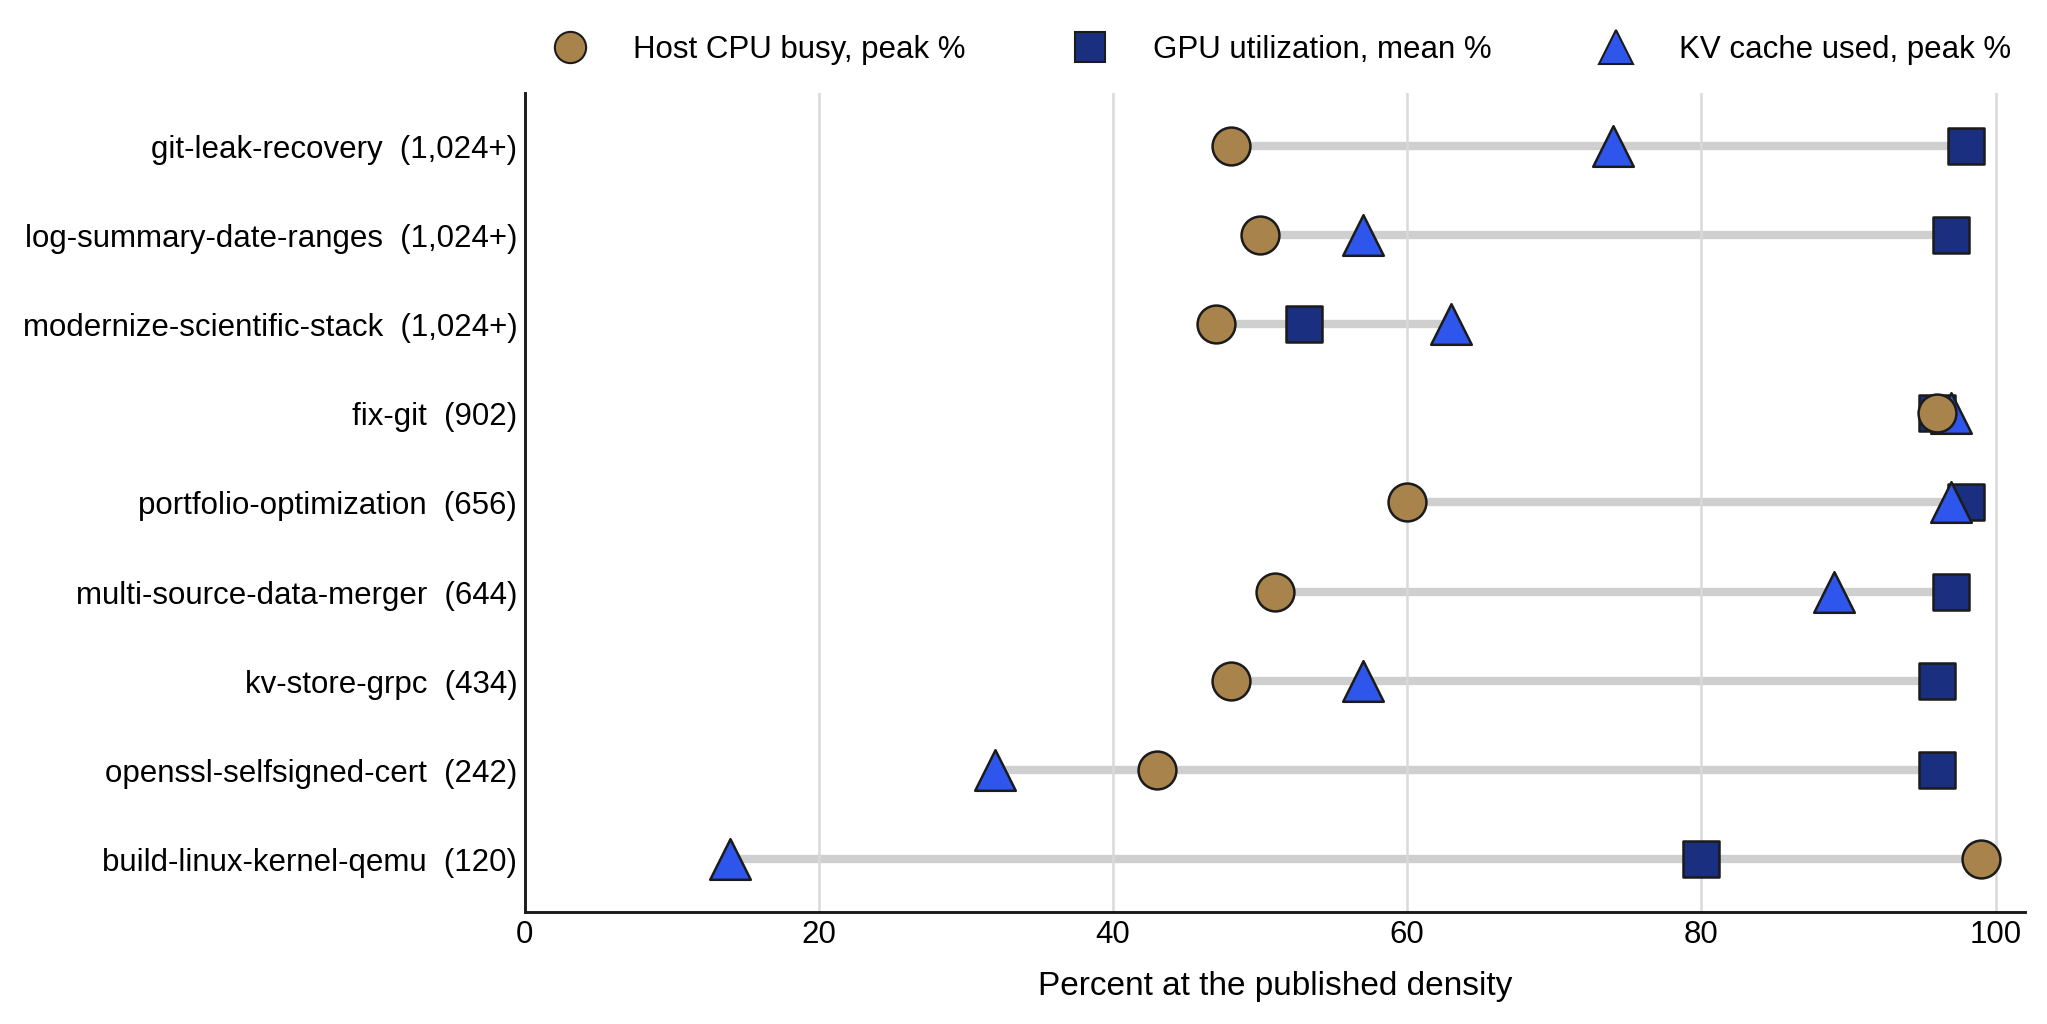
On inference-dominated and mixed work, two mechanisms combine at the boundary. The first is GPU compute: the mixture-of-experts model is decode-bound at these batch sizes and both accelerators are simply full. The second is a serving-configuration ceiling. Each vLLM replica admits 256 concurrent sequences, 512 across the two GPUs, and telemetry shows running requests pinned at exactly 512 on every level above 512 agents. A fleet larger than 512 can still be served, because agents spend much of their time in the shell and the verifier rather than inferring, but past that point every extra agent adds queueing.
Time to first token tells the same story in one number. It sits between 0.2 and 0.5 seconds at every rung up to 512 agents, then jumps to tens of seconds at the published densities above 512 agents, 16.6 seconds on fix-git at 902. The agents are waiting on the model, and the two Intel Xeon 6 6760P processors still had room at every published level: 902 concurrent sandboxes ran at an 8% mean host CPU, sandbox start-up p95 never exceeded 2.6 seconds, and host memory peaked at no more than 435 GB of the 1,056 GB reported. Two readings need their context: modernize-scientific-stack reached its published density with its GPUs only 53% busy and 37% of requests queued, so the admission limit rather than GPU compute set its pace, and fix-git's 96% host-CPU peak is brief bursts of hundreds of sandboxes running git at once against a mean of 8%.
Host CPU, GPU and KV-cache readings at each task’s published density
Key takeaway: On inference-dominated agent work, this configuration is bounded by the model-serving tier: two saturated GPUs and a 512-request admission limit. For most tasks, host CPU, memory and container admission retained capacity at every published density, so the next scaling step is serving capacity rather than more host. On compile-heavy work the same chassis binds on cores instead, which is why the work profile has to come before the sizing.
Two work profiles, two different walls
For every level the benchmark records how many CPU core-seconds the sandboxes consumed for each GPU-busy second the model replicas consumed. That ratio separates the nine tasks cleanly and predicts which tier will bind before a ladder is run. openssl-selfsigned-cert (0.36 : 1) and git-leak-recovery (0.45 : 1) are almost pure inference. fix-git (4.69 : 1) mixes real tool work with inference. build-linux-kernel-qemu (82 : 1) compiles and boots a Linux kernel: for every second the accelerator spends thinking, that fleet spends 82 core-seconds building, and it is the one task where the host rather than the serving tier sets the limit.
Work profile and binding tier at each task’s published density. Core-seconds are summed over every sandbox in the level, and GPU-busy seconds over both accelerators. Capacity results showing maximum qualified agent density, pass rate, confidence level, and latency compliance across nine coding-agent tasks.
Task
Core-seconds per GPU-busy second
Host CPU peak
GPU busy, mean
Binding tier at boundary
openssl-selfsigned-cert
0.36:1
43%
96%
Serving tier
git-leak-recovery
0.45:1
48%
98%
Serving tier
log-summary-date-ranges
0.78:1
50%
97%
Serving tier
kv-store-grpc
1.22:1
48%
96%
Serving tier
multi-source-data-merger
1.56:1
51%
97%
Serving tier
fix-git
4.69:1
96%
96%
Serving tier
modernize-scientific-stack
6.40:1
47%
53%
Serving slot limit
portfolio-optimization
15.05:1
60%
98%
Serving tier (preemption)
build-linux-kernel-qemu
82.19:1
99%
80%
Host CPU
Key takeaway: Eight of nine tasks are bounded by the serving tier and one, the kernel build, by host CPU. Sizing an agent platform therefore starts with the work profile: inference-dominated fleets need serving capacity, compile-heavy fleets need cores, and a mixed estate needs both measured rather than assumed.
The fix-git ladder in detail
fix-git is the reference task. The agent must recover commits that went missing after a checkout and merge them into master, at 1 CPU and 2,048 MB against a 900-second deadline. Attempt latency grows slowly to 512 agents and then steeply, and the knee coincides exactly with the point where the serving tier fills.
fix-git density ladder in ladder order. The 943 and 1,024 levels breached the 900-second ceiling, so 902 is the verified boundary. Agent-density benchmark results showing concurrent coding-agent capacity, latency, quality, resource utilization, power efficiency, and rack-scale projections for a Dell PowerEdge R770 platform running autonomous AI agents.
Agents
Result
Pass rate
p95 (s)
Tasks per min
TTFT (s)
GPU busy, mean
KV cache
1
Held
100%
20
2.8
0.2
34%
1%
12
Held
75%
60
8.1
0.2
77%
2%
32
Held
91%
69
21.9
0.2
83%
6%
128
Held
87%
169
38.5
0.2
89%
20%
256 †
Held
89%
264
32.5
0.3
78%
39%
512 †
Held
91%
451
33.2
0.5
80%
77%
902
Held
87%
891
51.6
16.6
96%
97%
943
Failed SLA
88%
916
54.5
18.7
96%
98%
1,024
Failed SLA
85%
989
56.7
24.2
96%
98%
The 902 and 943 rungs come from the binary search triggered when the core 1,024 rung failed; rungs at 2, 64 and 115 agents appear in the companion report. Host CPU peak sat between 44% and 56% from 32 to 512 agents and reached 96% at 902 agents, where the mean was 8%. Model output rose 22.5 times across the ladder, from 140 to 3,156 tokens per second. Daggered levels are straggler-distorted: one or two slow attempts stretched the goodput window, understating tasks per minute and mean GPU utilization at 256 and 512 agents while latency and pass rates are unaffected. No boundary level was distorted.
Key takeaway: A single Dell PowerEdge R770 admits a single-pass fleet of 902 concurrent fix-git agents, each completing its own work within a 900-second target (fleet start-up and verification excluded), bracketed by a failing level at 943, while 87% of attempts pass and 51.6 verified tasks per minute leave the server. Above the boundary the server keeps producing more work. It simply stops producing it within the promised time.
Task quality holds under load
Across the nine published densities the verifier pass rate is 85% to 99%. At every rung from 12 agents up to each boundary it stays inside the band the task shows at low density: 75% to 92% on fix-git, 75% to 92% on kv-store-grpc, and 86% to 100% on the other seven. Density moved latency and per-agent token rate. It did not move correctness.
One case is instructive rather than contradictory. On multi-source-data-merger at 1,024 agents, well above its 644-agent boundary, 664 of 1,024 agents hit the deadline and the pass rate fell to 33%. That is what deep oversubscription looks like on a single-pass fleet, and it is exactly the failure the latency gate exists to catch before publication. Pass rates describe how often this model solves these tasks, not how well the platform runs them.
Power and energy
Whole-node power comes from the PowerEdge R770 chassis ACPI power meter through hwmon, CPU package power from RAPL and GPU board power from DCGM, all sampled at two-second intervals on a common clock.
Node mean power stayed within 1.46 kW to 1.86 kW at the published densities, with instantaneous peaks to 2.3 kW, against about 1.0 kW at a single agent. That is a narrow envelope for a swing from 1 agent to 1,024, and it means the baseline dominates: most of the bill is present before the first agent starts work. Because the baseline is fixed, it amortizes as density rises. On fix-git, whole-node metered energy per passed task fell from 6.5 Wh at 1 agent to 0.60 Wh at 902, while verified output rose eighteenfold and model output 22.5-fold over the same range. Every task improved by roughly an order of magnitude between one agent and its boundary. The compile-heavy kernel build is the exception, at 7.6 Wh per verified task, because compiling and booting a kernel is simply a lot of work per verified result.
fix-git: power across the ladder, and whole-node energy per passed task. Energy is shown for the rungs whose rate figures are undistorted, all of which appear in Table 5; the power series covers every rung
This campaign configured a latency ceiling and a pass floor, but no goodput or energy ceilings, so the density floor here is economic rather than a gate result. An operator who sets an energy-per-task or throughput target will find that the density which fails it is the low one, and that is the opposite of the intuition that lower density is always safer. Running an agent fleet at low density is the expensive mistake.
How to read these figures
One host, one model, one serving layout. Every number is specific to Ornith-1.5-35B-A3B-FP8 on two single-GPU vLLM replicas with a 256-sequence admission limit each, so the method transfers but the constants do not.
This is not the model vendor's reference serving recipe. The model card recommends tensor-parallel 2 and documents a 262,144-token context window, while this campaign ran one replica per accelerator at tensor-parallel 1 with context at 131,072 tokens, because two independent replicas behind a router serve a large agent fleet better than one tensor-parallel instance.
The latency target is the task's own deadline. The deadline is checked between steps, so an attempt stopped by the deadline is recorded at the time its in-flight step returned and its recorded duration can exceed the deadline by one step. The p95 of a failing level can therefore exceed the deadline, as it does at 943 and 1,024 agents on fix-git. At every published level fewer than 5% of attempts were deadline-stopped, so the published p95 values, two of which sit within 1% of their ceiling, are the measured tail.
Single-pass fleets measure throughput conservatively at mid-ladder rungs, and exclude fleet start-up. A level's window ends with its slowest agent, so tasks per minute at the flagged levels understates steady-state throughput while latency and pass rates are unaffected. Bringing 902 sandboxes up took 117 seconds at p95, so an operator planning cold starts should add the ramp.
The three lower bounds are not a ceiling. git-leak-recovery, log-summary-date-ranges and modernize-scientific-stack held every rung including the top, so their figures should never be quoted as 1,024.
Read each published figure as the center of a band. Densities on this host reproduced across independent runs to within roughly 15% of agent count, and a small change in how many agents finish can move p95 across a ceiling.
Business impact
A validated agent-density measurement informs four infrastructure planning decisions directly: how many chassis a target fleet needs, how much rack power to allocate, where the next infrastructure dollar should go, and the density below which the platform is uneconomic to operate.
Size fleets by task profile, not by GPU count. On this configuration the published fleet sizes on inference-dominated and mixed work ran from 242 to more than 1,024 agents per chassis under each task's own attempt target, with the reference task, fix-git, at 902 concurrent agents, while a compile-heavy fleet sizes at roughly 120 agents with an 8-CPU cap each. A team that knows its task mix can derive chassis count from Table 3 and the energy-per-task curve from Figure 4, replacing estimate-based sizing that, based on this evidence, can overprovision by nearly an order of magnitude.
Invest in the tier that is actually binding. For inference-dominated fleets, raise the per-replica concurrency limit first, and once both GPUs are saturated, scale out to a second node rather than adding host capacity: at seven of the eight serving-bound boundaries host CPU peaked at or below 60% against means of 2% to 15%, host memory stayed below half of the 1,056 GB reported and sandbox admission p95 stayed under 2.6 seconds, so the two Intel Xeon 6 6760P processors carried the sandbox fleet with capacity to spare. Two tasks peaked above 90%: fix-git at 96%, a brief burst of hundreds of sandboxes running git against an 8% mean, and the compile-heavy kernel build at 99%, where the host is the binding tier. The attribution is inferred from utilization rather than from a harness bottleneck verdict, so confirming it would require intervening on the host quota and re-measuring. For compile-heavy fleets the reverse holds, and the kernel build's accelerators had roughly 20% headroom at 120 agents, so on that profile additional cores convert directly into additional agents. While mean CPU utilization remained low, tasks with high transient peaks (like fix-git) will eventually require host scaling to prevent burst-contention if serving limits are removed.
Plan rack power from node-scope measurement. Plans built from CPU and GPU counters alone would place the chassis about 30% too low, because node draw is 1.4 times the component sum. Provision the rack from node-scope measurement and treat the fixed baseline as the dominant term at low utilization.
Operate above the density floor. Every task's energy per verified result improved by roughly an order of magnitude between one agent and its boundary. The fixed platform baseline amortizes only when the machine is full, so a team that provisions generously and runs at low density pays it twice: once in capital and again in energy per completed task.
From server to rack: The agentic compute rack
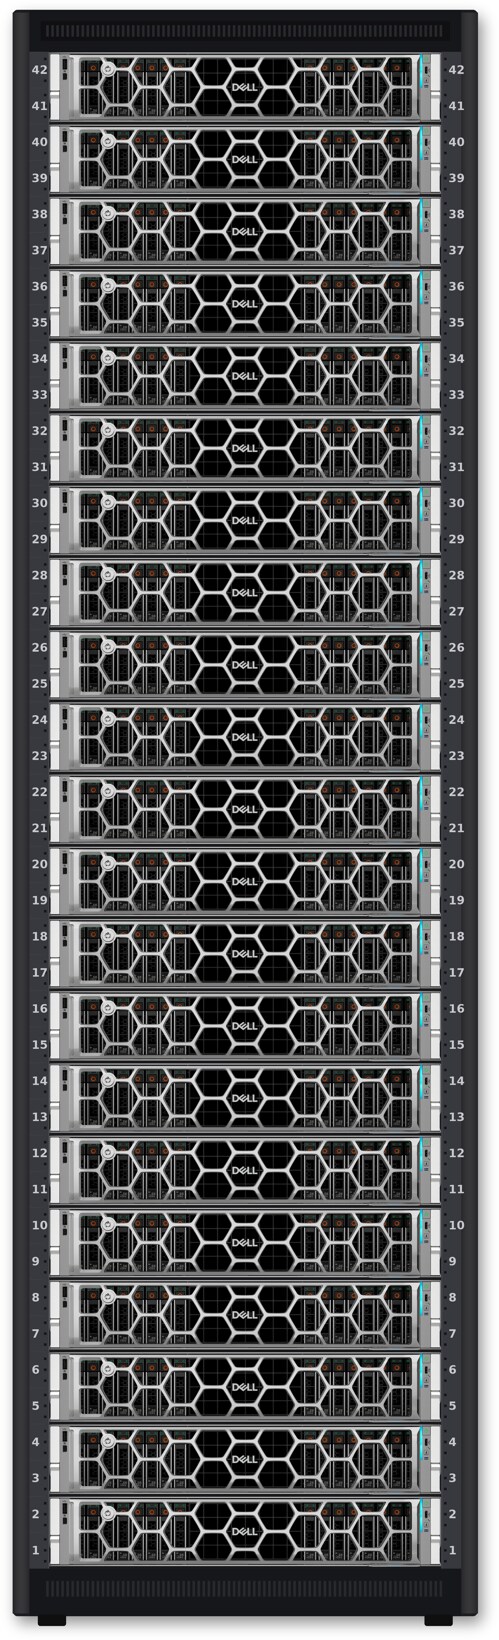
Every measurement in this paper was taken on one chassis, but enterprises deploy, power and budget agent platforms one rack at a time. The tested architecture is self-contained: agents, sandboxes, both model replicas, the router and telemetry all run on a single Dell PowerEdge R770, so each server is an independent agent cell with its own serving tier. This section projects the measured results linearly to a fully populated 42U rack of 21 R770 servers, each configured exactly as the system under test. The rack figures are projections, not a rack-scale measurement, and carry the same task and service-level qualifications as the node figures they are built from.
Rack composition
Across 21 servers, the system under test (Table 8) becomes 42 Intel Xeon 6 6760P processors with 2,688 cores and 5,376 logical CPUs for the sandbox fleet, 42 NVIDIA RTX PRO 6000 Blackwell GPUs with 4,032 GB of GDDR7, 21 TB of DDR5 and 42 independent vLLM replicas admitting 10,752 concurrent sequences. Whole-node metered power scales to about 21 kW at one agent per server, 30.7 to 39.1 kW mean at the published densities, and 48.3 kW if every server reached its 2.3 kW instantaneous peak at once.
The agentic compute rack: 21 Dell PowerEdge R770 servers in a 42U rack.
Projected agent capacity per rack
Because each server runs its own fleet and serving tier, rack capacity is the published node density multiplied by 21 (Table 6). The spread on one chassis carries straight through: the same 42U holds about 2,500 compile-heavy kernel-build agents or more than 21,500 agents on the three tasks that never reached a limit. A rack has an agent capacity only once the task and the service level are attached to it.
Projected agent capacity of a 21-server agentic compute rack. Lower bounds stay lower bounds at rack scale and should not be quoted as 21,504. Each figure inherits the roughly 15% reproducibility band of the node figure it is built from. Service-level-qualified agent densities across nine coding tasks on a Dell PowerEdge R770.
Task
Work profile
Per server (Table 3)
Per rack, 21 servers
Binding tier
git-leak-recovery
Inference-dominated
1,024 or more
21,504 or more
Serving tier
log-summary-date-ranges
Inference-dominated
1,024 or more
21,504 or more
Serving tier
modernize-scientific-stack
Mixed
1,024 or more
21,504 or more
Serving slot limit
fix-git
Mixed
902, verified
18,942
Serving tier
portfolio-optimization
Compute-heavy
656
13,776
Serving tier, preemption
multi-source-data-merger
Mixed
644, verified
13,524
Serving tier
kv-store-grpc
Mixed
434
9,114
Serving tier
openssl-selfsigned-cert
Inference-dominated
242
5,082
Serving tier
build-linux-kernel-qemu
Compute-heavy
120
2,520
Host CPU
Projected from the measured single-server fix-git boundary (Table 5) across 21 servers. Table summarizing projected rack-scale fix-git performance, throughput, power consumption, and energy efficiency based on a 21-server deployment.
Concurrent agents (900 s target)
Verified Tasks/Min
Rack Mean Power (kW)
Energy per Verified Task (Wh)
18,942
~1,080
~39
0.60
Rack power sets the server count
Because node draw is about 1.4 times the CPU and GPU component sum, the number of servers a rack supports should be read from whole-node measurement. Table 7 provisions each server conservatively to the 2.3 kW instantaneous node peak, and alternatively to the 1.86 kW highest boundary mean.
Servers and projected agents per rack by power budget, capped at 21 servers by rack space. Provisioning to the node peak assumes every server peaks at once and is the conservative column. The table shows projected numbers of Dell PowerEdge R770 servers, fix-git agents, and kernel-build agents supported at rack power budgets from 15 kW to 50 kW, based on both 2.3 kW peak and 1.86 kW mean server power assumptions.
Rack power budget
R770s at 2.3 kW peak
fix-git agents
Kernel-build agents
R770s at 1.86 kW mean
fix-git agents
15 kW
6
5,412
720
8
7,216
20 kW
8
7,216
960
10
9,020
30 kW
13
11,726
1,560
16
14,432
40 kW
17
15,334
2,040
21
18,942
50 kW
21
18,942
2,520
21
18,942
At 31 to 39 kW mean and up to 48 kW peak, a full rack sits in high-density territory, so confirm power distribution and cooling against the full-rack figure before deployment. In lower power envelopes the rack is power-bound before it is space-bound, and the 15 to 30 kW rows of Table 7 are the realistic planning points.
Designing the rack around the work profile
Serving-bound racks. For inference-dominated and mixed fleets the rack ceiling is 42 saturated GPUs and 42 replica admission limits. The first increment is a serving-configuration change on every server, raising per-replica concurrency; once both GPUs in each server are saturated, further capacity comes from additional servers. Host CPU means stayed at 2% to 15%, but fix-git's 96% bursts mean host headroom should be re-measured once serving limits are raised.
Core-bound racks. Compile-heavy fleets bind on cores: a full rack projects to 2,520 kernel-build agents with roughly 20% accelerator headroom, so more cores per server convert directly into rack density.
Mixed estates. This campaign ran one task per server, so plan a mixed estate as servers or racks dedicated to each profile, sized from their own row of Table 6. Co-locating profiles on one server was not measured.
The density floor scales with the rack. A full rack draws about 21 kW at one agent per server, so running it sparsely spreads that baseline across very little verified work. Operating each server near its boundary is the largest lever on rack-level energy per verified task.
Reading the rack figures. Rack figures multiply single-server results by 21 and exclude shared rack services such as top-of-rack networking, the egress proxy, image distribution and central telemetry, which must be sized separately. Reserving 2U for top-of-rack switching leaves 20 servers and scales every figure by 20/21, for example 18,040 concurrent fix-git agents.
Key takeaway: A platform team ultimately has to answer how many racks, at what power, deliver a target fleet within its service level. On this evidence, a 21-server agentic compute rack of Dell PowerEdge R770 servers with Intel Xeon 6 processors delivers between about 2,500 and more than 21,500 concurrent coding agents depending on the work profile, at about 31 to 39 kW. For serving-bound racks, the first upgrade is a serving-configuration change on every server, and capacity beyond that comes from adding servers.
Conclusion
The question of how many coding agents a server can run has no single answer, and this campaign shows why in measured terms. On one Dell PowerEdge R770 with two Intel Xeon 6 6760P processors and two NVIDIA RTX PRO 6000 Blackwell GPUs, nine tasks produced nine defensible answers between 120 and more than 1,024 concurrent agents, each tied to a stated latency target and a verified pass rate. The reference figure is 902 concurrent fix-git agents within a fifteen-minute attempt-latency target, bracketed by a failing level at 943.
One methodological finding travels further than any other capacity number. The machine does not say when to stop. On the reference task, verified output kept rising above the published boundary and no subsystem failed, so only an explicit service level converts a smooth curve into a figure an operator can deploy against. What generalizes beyond that is the shape of the result. Inference-dominated agent work binds on the serving tier while the host retains capacity. Compile-heavy work binds on cores, where core count converts directly into agent density and the accelerators retain headroom. Task quality held at every published density, and energy per verified task fell by roughly an order of magnitude as the fleet grew. Both tiers are therefore sized from the measured work profile and the service level, not from accelerator count or a fixed CPU-to-GPU ratio. Those are the facts a platform team needs to size a fleet, choose the next investment and plan the rack, and this work measured them rather than inferring them.
Next steps
Three steps convert this measurement into a plan for a specific estate.
Profile the task mix before sizing anything. Core-seconds per GPU-busy second predicts whether the estate will bind on serving capacity or on cores, and it is cheaper to measure than a full ladder.
Set the latency target first, then measure capacity against it. A density without a stated promise is not a planning number, and teams with a target tighter than fifteen minutes should read their own figure off the fix-git ladder in Table 5 rather than adopting the published boundary.
Raise the serving ceiling before adding hardware. On this configuration the per-replica concurrency limit is the first adjustment, and it is cheaper than a second chassis. Once both GPUs are saturated, the next step is another node, and the Intel Xeon 6 host tier was never the constraint at any serving-bound boundary.
For teams already standardized on Dell PowerEdge for AI infrastructure, raising agent density on this configuration is a serving-tier configuration change rather than a re-platforming exercise.
Appendix: system under test
CPU, core and thread counts, memory, kernel and GPU identity were read from the machine at run time and are embedded in every evidence bundle. Server model, DDR generation, storage and TDP are from the platform specification.
System under test: hardware and software stack. The table lists the system-under-test configuration, including Dell PowerEdge R770 hardware specifications, Intel Xeon 6 processors, NVIDIA RTX PRO 6000 Blackwell GPUs, storage, operating system, Ornith-1.5-35B-A3B-FP8 model, vLLM serving configuration, and agent sandbox framework.
Component
Specification
Server platform
Dell PowerEdge R770 rack server
CPU
2 x Intel Xeon 6 6760P processors, 64 cores and 128 threads per socket, 330 W TDP. 128 physical cores, 256 logical CPUs
Memory
1 TB DDR5, 1,056 GB reported
GPU
2 x NVIDIA RTX PRO 6000 Blackwell Server Edition GPUs, 96 GB GDDR7 each
Storage for run data
3.2 TB NVMe volume for run artifacts and sandbox layers
Operating system
Ubuntu 24.04 LTS, kernel 6.8.0-138-generic
Model
ornith-ai/Ornith-1.5-35B-A3B-FP8, revision 0e048080. A 35B-parameter mixture of experts with roughly 3B parameters active per token, FP8 weights
Model serving
vLLM v0.27.1, pinned by digest. Two replicas, one per GPU, tensor-parallel 1, behind one shared router. Context 131,072 tokens, GPU memory target 0.90, 256 concurrent sequences per replica
Agent framework and sandbox
deepagents on LangGraph, ReAct loop, one Docker sandbox per agent. Task content baked into the image, held-out tests copied in only at grading time. CPU quota and memory limit enforced per container, direct external egress blocked, and the verifier runs in the same container after the agent finishes
The nine qualified tasks, from Terminal-Bench. Task content is pinned by hash and unchanged across the campaign. The table summarizes the nine benchmark tasks, including git recovery, log analysis, software modernization, portfolio optimization, data merging, gRPC service implementation, certificate generation, and Linux kernel compilation workloads used to evaluate agent density.
Task
What the agent must do
git-leak-recovery
Recover a secret removed by a history rewrite and purge it without touching other commits.
log-summary-date-ranges
Aggregate severity counts from dated log files across several rolling date ranges.
modernize-scientific-stack
Port a legacy climate-analysis script to current numpy and pandas APIs and declare dependencies.
fix-git
Recover commits that went missing after a checkout and merge them into master.
portfolio-optimization
Re-implement a nested-loop portfolio risk model as a C extension, within 1e-10 of the Python baseline and at least 1.2x faster at 5,000+ assets.
multi-source-data-merger
Merge user records from JSON, CSV, and Parquet sources, resolving conflicts.
kv-store-grpc
Define a key-value service in protobuf, generate gRPC stubs and run a conforming server.
openssl-selfsigned-cert
Generate a 2048-bit RSA key and self-signed TLS certificate with the required file permissions.
build-linux-kernel-qemu
Build Linux 6.8 from source, generate an initramfs and boot it under QEMU.
Reproducibility
The campaign ran auto qualification in service-level limit mode on a closed single-pass fleet, with a five-level boundary search budget. Confirmation runs were disabled, so each boundary was measured once. High confidence in Table 3 means the figure reproduced across independent runs with clean telemetry, and Medium means two or more runs agreed within roughly 15%, with any outlier identified. Latency is judged on agent work only, from release to agent finish, with fleet ramp and the verifier excluded. One reading rule applies to the kernel build: it changed its declared shape on 28 August 2026, from 16 to 8 CPUs per agent, so the 120 figure is comparable only with other post-change runs, both of which found the latency ceiling at 128. Run identifiers and per-run evidence bundles are listed in the companion report and available on request.
Terms used in this paper
Agent attempt p95 is the 95th-percentile time from an agent's release to the end of its own work, over every attempt in the level including those stopped by the deadline, excluding fleet start-up and the verifier; the latency service level is judged on it. Verified goodput is attempts that passed the task's verifier, per minute of the goodput window, which runs from fleet release to the last passing verdict. The level window, from fleet release to the last verdict of any attempt, bounds telemetry, power and GPU-busy accounting. A figure is verified when a failing level exists above the published one and the interval between them was searched, and a lower bound when the level above was not valid or the ladder ended.
References
Agent Density on Dell PowerEdge R770. Benchmarking report, campaign 2026-08-29-agents, September 2026. Companion technical report to this paper, including per-task ladders and the full gate set.
Agent Density campaign manifest and per-run evidence bundles, runs of 26 August to 1 September 2026. Run identifiers listed in the companion report. Available on request.